 AI interpretability is the effort to understand why an AI model does what it does, and a new claim says that job may be much easier than researchers feared. Nick Cammarata, a former OpenAI researcher who now works at the interpretability startup Goodfire, published a 26,000-word essay on October 15, 2026, arguing that neural networks are far more readable than the field believed. The essay, titled “Neural Networks Are Already Clean,” reopened a longstanding debate within days.
One disclosure comes first. The New York Times covered this claim on October 27, 2026, in an article by Cade Metz, but that article is paywalled and only its opening portion was accessible to PetaTech24. No bypass or sign-in was attempted. This article is therefore a corroborated synthesis: it uses the accessible opening of the Times piece, Cammarata’s own essay, and reporting by The Decoder and MIT Technology Review, with each AI interpretability claim attributed to its source.
For AI interpretability, the stakes are practical. If researchers can read a model’s internal parts directly, they may spot deceptive behaviour, target fixes, and check safety claims with evidence rather than guesswork. If they cannot, the most powerful systems stay partly opaque even to the people who build them. Cammarata argues the field was looking at the problem the wrong way. Other researchers say the evidence is preliminary, and the argument is far from settled.
The Short Version: AI interpretability in One Claim
- Cammarata argues most neurons in modern networks do one understandable job, and the tangled appearance of older models came mostly from weak tools and outdated architecture.
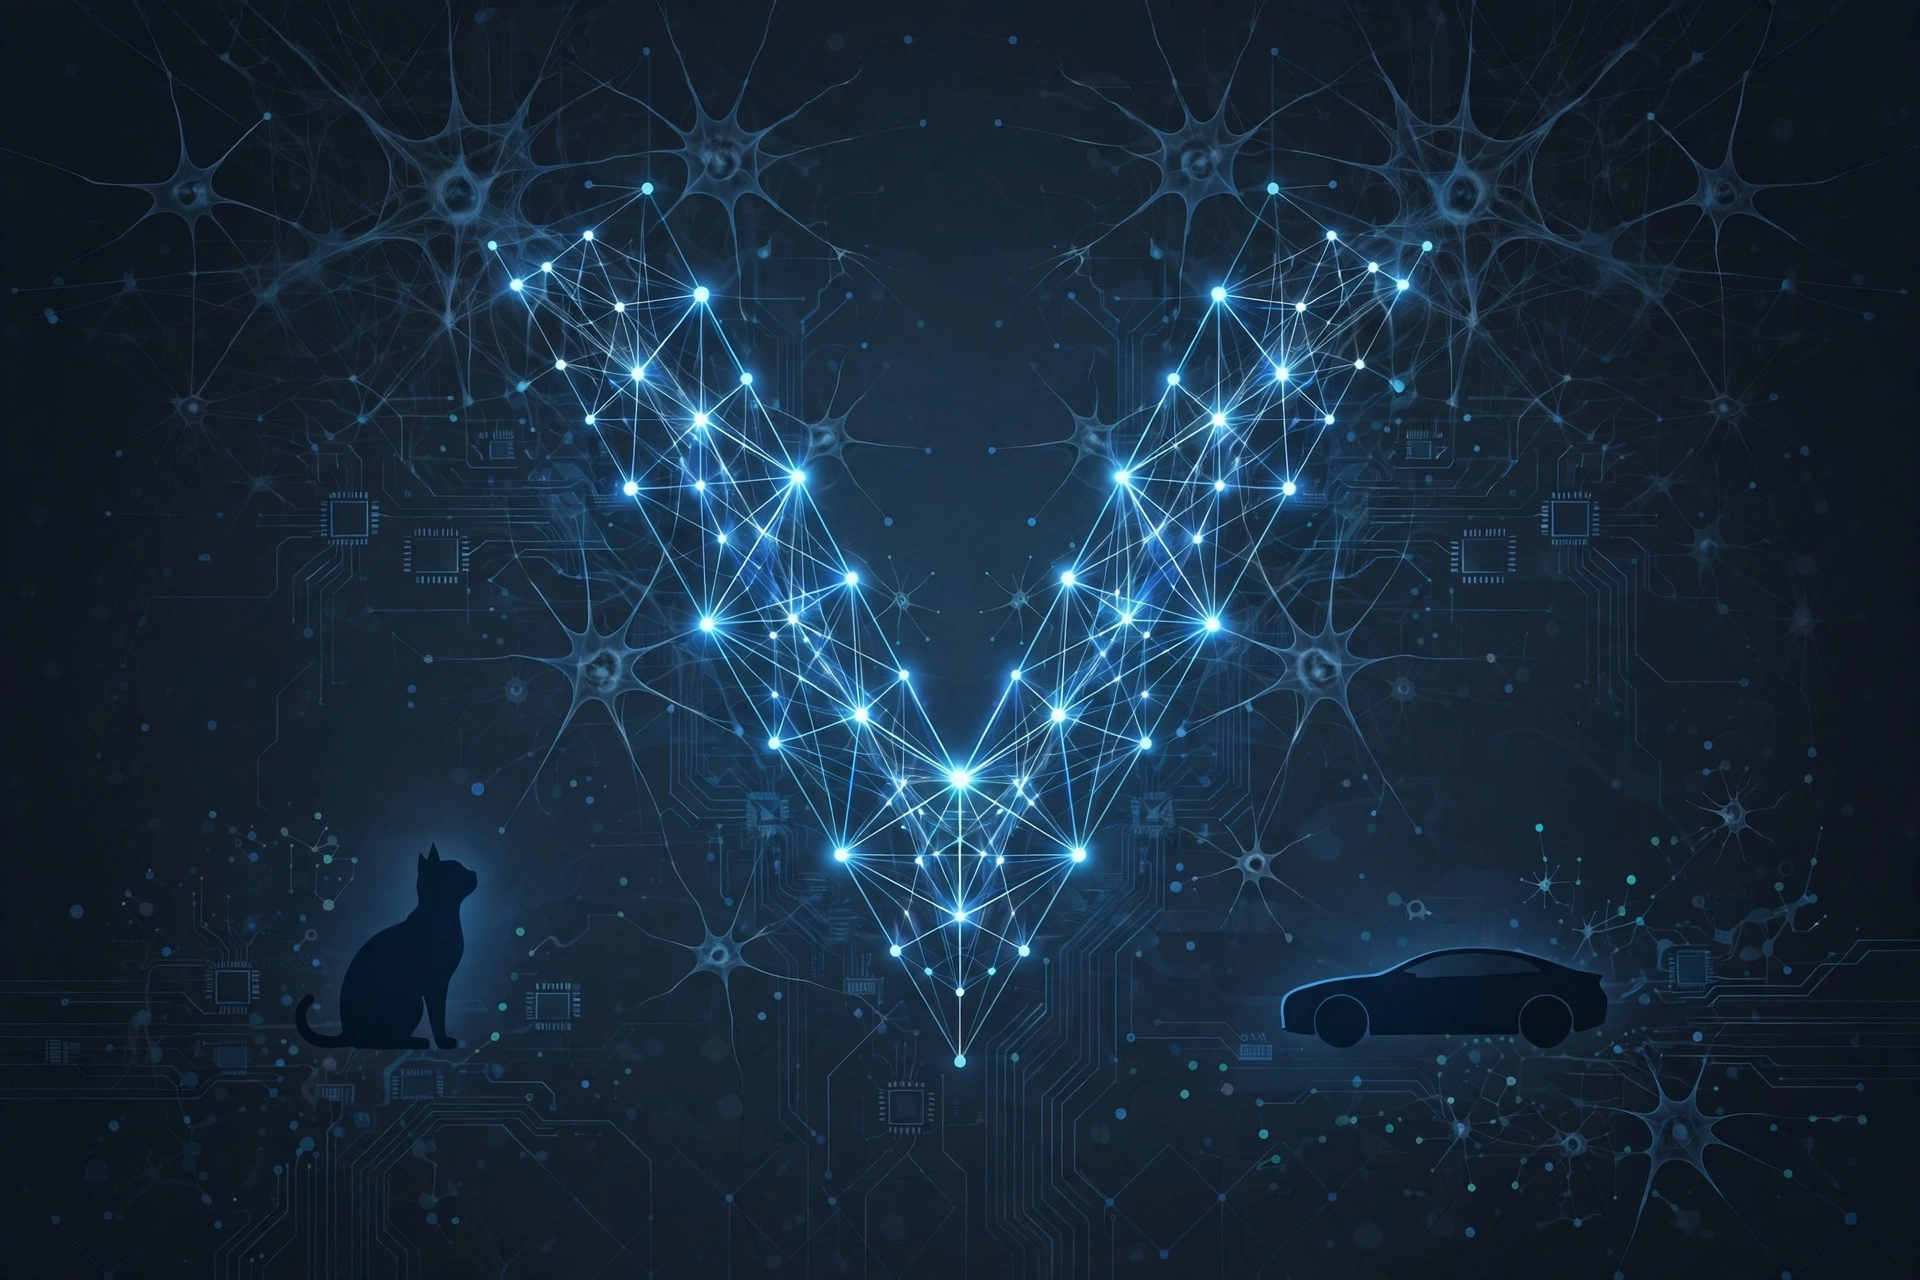
- His central example is old: a neuron in Google’s 2014 InceptionV1 image model seemed to respond to both cat faces and car fronts. Cammarata now says it detects a V shape shared by both.
- In preliminary audits of the openly available Qwen3-32B, he estimates roughly 90% of neuron poles have one main job, but calls the figure a broad pointer, not a precise score.
- Sceptics, including Google DeepMind’s Neel Nanda and Stanford’s Chris Potts, say the work does not show AI interpretability is close to solved. The companion paper is unreleased, and outside researchers have not confirmed the results.
- The claim rests on an informal essay and preliminary audits, not a peer-reviewed paper. Independent replication will decide how much of it survives.
Why You Should Care About AI interpretability
AI interpretability tries to do more than watch what a model outputs. As The Decoder explains, it aims to trace how the model arrives at its answers internally, so each artificial neuron would stand for a recognizable concept. In practice, many neurons seemed to fire on unrelated things, which researchers call polysemanticity. That pushed AI interpretability research toward a workaround: train a second model, such as a sparse autoencoder, to pull the concepts apart, and study that model instead of the original.
Cammarata helped shape the old view. With Chris Olah, he co-wrote the 2020 Distill paper “Zoom In,” which introduced the first superposition circuit. In 2023, he started an automated interpretability project at OpenAI, where only about 1.7% of neurons counted as understandable, even by the most generous measure, according to The Decoder and Cammarata’s essay. That low figure helped convince the field that reading neurons directly was a poor starting point.
The safety argument follows from that history. Apart from monitoring chains of thought that keep getting less reliable, there are few ways to tell whether a model is deceiving people or behaving dangerously, The Decoder reports. Cammarata doubts that alignment, the work of steering AI toward human goals, can be solved without AI interpretability, because otherwise researchers do not know what they are building. If humans can read the network directly, he writes, they can see deception too, and errors might be fixed in a targeted way.
The V-Shape Clue in InceptionV1
The essay opens, in Cammarata’s own words, with a short piece of good news: “I think I have good news about the nature of neural networks.” The rest argues that the canonical AI interpretability evidence for tangled networks was misread, and the AI interpretability debate now turns on whether that re-reading holds. Its most vivid exhibit is the neuron that appeared to treat cars like cats. InceptionV1 could reliably identify common objects in photographs, the Times opening notes, but the calculations identifying a car resembled those recognising a cat.
Cammarata’s answer is a shared shape. He found that one calculation pinpointed a V shape present both at the front of a car and on a cat’s face, according to the Times opening. Pointed shapes like fox snouts or flames activate the neuron, The Decoder reports, while round shapes like the letter O push its activation negative. A neuron has two poles, a strongly positive side and a strongly negative side, and here the two sides point in opposite directions around the same shape.
A second old example in AI interpretability gets the same treatment. In “Zoom In,” a car feature appeared to spread into unrelated dog neurons, read as the network hiding the car for later neurons to read back. Cammarata now says nothing reads that combination, and the grouping follows pose: the circuit groups cars and dogs by which way they face the camera. He also blames the picture-making tool of the time, which often found dog images because the training data contained many dogs, hiding the shared patterns underneath.
The retraining test is his strongest check on his own old work, and a central piece of evidence for AI interpretability optimists. Architectural problems made InceptionV1’s later layers overflow, he writes, and weak tools amplified the problem. With ordinary improvements, and no change to model size or training data, 99% to 100% of neurons in the last layer are easily interpretable. He trained versions across a 300-fold range in size and reports the same broad legibility at every scale. With less room, he argues, neurons cover coarser concepts rather than packing unrelated things together.
Recursive Generalization, Explained Plainly
Cammarata calls the remaining pattern recursive generalization, and it is his alternative explanation at the heart of the AI interpretability claim. A neuron learns a concept, then extends it to related ones, the way a branch sprouts side shoots. His example, given in the essay itself, is a neuron that detected the letter sequence “iy,” grew to detect “diy,” and then responded to “do it yourself,” which does not contain “iy” at all. The link is meaning, carried step by step, rather than an arbitrary mixture.
The same idea covers subtler cases. The essay describes neurons that track feelings and social cues, which often fire not on the words that carry the feeling, but on punctuation, like commas, where the model summarizes what a sentence meant. Read in isolation, the firing pattern looks like a jumble. Read with neighbouring neurons, upstream causes, downstream effects, and steering tests, Cammarata writes, the explanations keep pointing to the same place. That is his case for AI interpretability through studying networks directly, with agents running checks at a scale no human team could match.
The language-model numbers need careful handling, and they are the weakest link in the AI interpretability argument until replication arrives. In preliminary audits of Qwen3-32B, Cammarata estimates roughly 90% of neuron poles have one main job, often with small related offshoots, about 7% have two related jobs, and only 2% to 4% are not yet understood. He stresses that the share depends on thresholds for weak activations and on what counts as one thing. Goodfire says it sees similar results in models with up to trillions of parameters, including Kimi K3, which the companion paper will cover.
Numbers to handle with care
Cammarata does not introduce a fundamentally new method, The Decoder notes. He returns to the field’s original approach of studying neurons directly, with better tools, larger models, and automated agents. Borrowing from Rich Sutton’s “Bitter Lesson,” he concludes that simple investigation at massive scale beats clever decomposition methods. If direct AI interpretability study works, labs may not need a separate decomposition model before they can learn anything useful.
AI interpretability: What the Sceptics Say
Neel Nanda, who leads the interpretability team at Google DeepMind and is considered one of the founding figures of mechanistic interpretability, is far more measured than the celebratory reaction online. The Decoder reports that Nanda calls Cammarata’s work interesting but says it does not really change the big picture for AI interpretability. Neuron-based analysis could help with practical questions, like why a model did something questionable, and it is much easier to apply to frontier models. But Nanda does not buy the idea that the field is close to being fully cracked.
Nanda’s technical objection is specific. He argues that language models store far more facts than they have neurons, and weak activations in particular likely hold much of that information. An audit focused on the strongest responses could therefore miss important content. He also doubts that findings from small image models carry over to language models, which he expects to memorize far more. Part of the AI interpretability dispute is definitional: Nanda sees Cammarata as agreeing that models can represent more concepts than they have dimensions, while disputing only the claim that networks arbitrarily pack completely unrelated things together.
Chris Potts of Stanford University, who leads a team trying to understand how large language models work, goes further, and his caution is central to the AI interpretability debate. MIT Technology Review reports Potts calling what Cammarata shared little more than a hunch, and quotes him saying that, as far as he can tell, nothing about the blog post makes the problems any easier. Jacob Hilton of the Alignment Research Center, as reported in secondary summaries, estimates researchers understand less than 0.01% of what happens inside top models, and argues that explaining individual neurons does not explain how they combine into circuits. Liv Gorton welcomes more understandable networks but argues that superposition, in her sense of holding more ideas than neurons, is not contradicted by branching neurons.
The enthusiastic reaction deserves the same care as the sceptical one. Roon, an OpenAI employee who posts under that pseudonym, wrote that the work may be remembered as a major moment in scientific history, The Decoder reports. Even Roon has reservations, The Decoder notes: others still need to confirm the results, and AI interpretability breakthroughs will also push AI capabilities forward. Cammarata himself is more cautious than some admirers. He labels his broadest conclusion, that understanding models could prove much easier soon, highly speculative, and puts his confidence in the proposed learning process at maybe 85% sure, according to the Implicator’s account of the essay.
Confirmed vs Reported vs Unknown
Confirmed: Cammarata published the essay “Neural Networks Are Already Clean” on October 15, 2026, through Goodfire, at about 26,000 words. He co-wrote the 2020 “Zoom In” research with Chris Olah, and his 2023 OpenAI project found about 1.7% of neurons understandable by its most generous measure. The Times piece by Cade Metz was published on October 27, 2026, and only its opening was accessible. The Decoder reported the AI interpretability debate on October 16, 2026, and MIT Technology Review interviewed Cammarata on October 22, 2026.
Reported: the V-shape reading, the pose explanation, and the Qwen3-32B audit figures are reported in the essay and secondary coverage. The responses from Nanda, Potts, Gorton, and Hilton are reported positions, not peer-reviewed findings. The claim of similar results in models up to trillions of parameters is Cammarata’s report in the essay, pending the companion paper.
Unknown: whether independent researchers can reproduce the audit figures on Qwen3-32B or frontier models, whether weak activations change the picture, and whether image-model findings transfer to language models. Also unknown is whether AI interpretability research on single neurons can explain circuits and behaviour well enough to support safety decisions. No source reviewed sets a date for resolution, and none claims deception detection or alignment is now solved.
What Happens Next
Three checks will test the claim better than more commentary. First, the technical companion paper, not yet released, should show the language-model experiments in enough detail for other researchers to judge the methods and thresholds. Second, independent replication matters most: Qwen3-32B is openly available, so other researchers can run the same checks, and Goodfire’s stake in the thesis makes outside confirmation especially important. Third, the field will watch whether other labs report similar legibility, or whether weak activations and circuit-level questions restore the older, harder picture. A claim that networks are “already clean” can easily harden, in retelling, into a claim that the hardest problem is solved. Cammarata’s essay does not make that stronger claim, and the AI interpretability debate will be decided by evidence, not by enthusiasm.
FAQ: AI interpretability Questions Readers Are Asking
What does AI interpretability mean in plain language?
AI interpretability means tracing how a model’s internal parts produce an answer, so researchers can explain a decision in terms of neurons and circuits rather than only judging the output. The debate here is whether those parts are readable directly, or must first be untangled by a second model.
Has the hardest problem in AI been solved?
No. No source reviewed claims that. Cammarata argues the problem may be much more tractable than feared, sceptics say the evidence is preliminary and unreplicated, and the author himself calls his broadest conclusion highly speculative. Treat the AI interpretability claim as an open hypothesis with striking examples, not a solved problem.
What is superposition, and why does it matter here?
Superposition is the theory that a network short of neurons packs unrelated concepts into the same neurons because they rarely interfere, leaving a knot to unfold before study. Cammarata argues the canonical examples were misread, and recursive generalization explains most apparent mixture. Nanda still thinks superposition is real, at least for factual storage, so the theory has not been disproven.
What would settle the debate?
A released companion paper with methods and thresholds, independent replication on Qwen3-32B and frontier models, and evidence that direct neuron study explains circuits and behaviour, including weak activations. Until those checks exist, the responsible summary is a bold, well-argued claim awaiting the confirmation it needs.
The Takeaway
Cammarata has given the field a testable story: a famous neuron that looked like two jobs is really one shape, old tools made old models look knotted, and modern networks may reward direct study at scale. The examples are specific, the author corrected his own earlier work in public, and the audit numbers are stated with their caveats. That is why the AI interpretability essay landed with force, and why it deserves serious checking rather than instant celebration or dismissal.
The sceptics have given the field the right tests in return: reproduce the audits, account for weak activations, show the circuits, and prove that image-model lessons transfer to language models. Until those tests report back, PetaTech24’s assessment is that this is a promising claim in search of confirmation. For AI interpretability, the problem has not been declared solved by anyone whose evidence PetaTech24 could verify. The next evidence to watch is the companion paper, and the first independent replication that either confirms or complicates the 90% figure.
Sources and Attribution
- Nick Cammarata, Goodfire, “Neural Networks Are Already Clean,” October 15, 2026. Primary essay; all essay claims attributed to Cammarata. Read the essay at Goodfire.
- The Decoder, “Is AI interpretability close to a breakthrough? A new essay has researchers divided,” October 16, 2026. Reporting on the essay, the V-shape reading, the Qwen3-32B figures, and Nanda’s response. Read the Decoder report.
- The New York Times, Cade Metz, “Did the Hardest Problem in A.I. Just Get Much Easier?”, October 27, 2026. Paywalled; only the opening portion was accessible, and no bypass or sign-in was attempted. Times article page.
- MIT Technology Review, Will Douglas Heaven, interview with Nick Cammarata, October 22, 2026. Reporting on the essay’s reception and Chris Potts’s response. No URL verified; listed by publication, author, and date.
- Implicator, “Goodfire’s Cammarata Says AI Neurons Are Readable After All,” October 16, 2026. AI-generated summary reviewed by an editor; used only for the essay’s stated confidence levels and Gorton’s definitional point, cross-checked against the essay and The Decoder. Read the Implicator summary.
- Olah, Cammarata, et al., “Zoom In: An Introduction to Circuits,” Distill, 2020. Original superposition circuit research, as cited in the essay and The Decoder.